Mid-cycle delays feel catastrophic because they arrive after you've already invested time, trust, paperwork, and emotional bandwidth. I've seen smart applicants and capable coordinators torch a perfectly salvageable mission because they treated a yellow-flag delay like a fatal red alert. Wrong move.
Here's the better approach: map the delay to the exact stage, decide whether you're dealing with a fixable process problem or a true threshold breach, and act on a clock. Fast, but not frantic. This guide is built to tell you exactly when you should stay calm, when you should push, and when you should admit the timeline is actually in danger.
The Timeline Model (So You Don't Panic at the Wrong Step)
At this point you should stop calling everything "behind." That word is useless. A mission doesn't simply drift. It drifts at a specific step, for a specific reason, owned by a specific person or system.
Use this sequence:
Intake
- Requirements confirmed
- Basic fit established
- Initial documents requested
Missions Setup
- Scheduling opens
- Capacity is tentatively assigned
- Coordinators, applicants, or liaisons align calendars
Verification
- Documents checked
- Eligibility confirmed
- Availability re-validated
- Missing items flagged
Submission/Commit
- Final packet or commitment sent
- Internal approvals completed
- Dates locked
Match/Placement
- Placement confirmed, denied, or waitlisted
- Contingency plans activated if needed
Operationally, "mid-cycle" usually means you are past intake and setup, but not yet securely committed. In plain English: you thought you were moving forward, but key confirmation still hasn't happened. That's the danger zone.
Now sort the delay into two buckets:
Bucket 1: Cause of delay
- Process: someone hasn't reviewed, replied, routed, or updated the system
- Capacity: no slot, no staffing, no supervising availability, no room
- Documentation: missing, expired, inconsistent, or rejected materials
Bucket 2: Timing severity
- Early warning: things are slowing, but deadlines haven't broken
- Threshold breach: a promised date passed, verification failed, or submission window was missed
That distinction matters. A process lag in early warning mode is annoying. A missed submission window is a real problem.
Week-by-Week: A 4-Week Mid-Cycle Playbook (Fix First, Then Escalate)
At this point you should assume most delays are diagnosable within 7-10 days. Not months. Not "let's circle back later." That kind of vague politeness kills options.
Week 1: Diagnose the bottleneck
Your only job this week is clarity.
Coordinator checklist
- Confirm the exact current stage
- Identify the last completed action with a timestamp
- Name the current owner of the stuck step
- Review all required documents for completeness
- Check whether the delay is process, capacity, or documentation
Applicant/liaison checklist
- Re-read every instruction sent so far
- Verify expiration dates, signatures, and file versions
- Confirm your availability is still accurate
- Send one clean status email with numbered questions
- Ask for one next action and one target date
If nobody can tell you what is pending by the end of Week 1, that's already a systems problem.
Week 2: Close gaps and re-commit
Now you fix what's fixable.
Coordinator
- Return incomplete packets with specific deficiencies
- Reconfirm staffing or slot availability
- Trigger internal review on anything sitting idle
- Replace vague updates with date-specific commitments
Applicant/liaison
- Resubmit corrected materials in one batch
- Attach the newest version only
- Summarize changes in bullet points
- Ask for confirmation of receipt
- Request verification completion by a defined date
This week is where a lot of people get lazy. Don't. "Just checking in" is a weak email. Send an email that moves the file.
Week 3: Escalate intelligently
At this point you should escalate only with evidence, not emotion.
Coordinator
- Notify the decision-maker above the current bottleneck owner
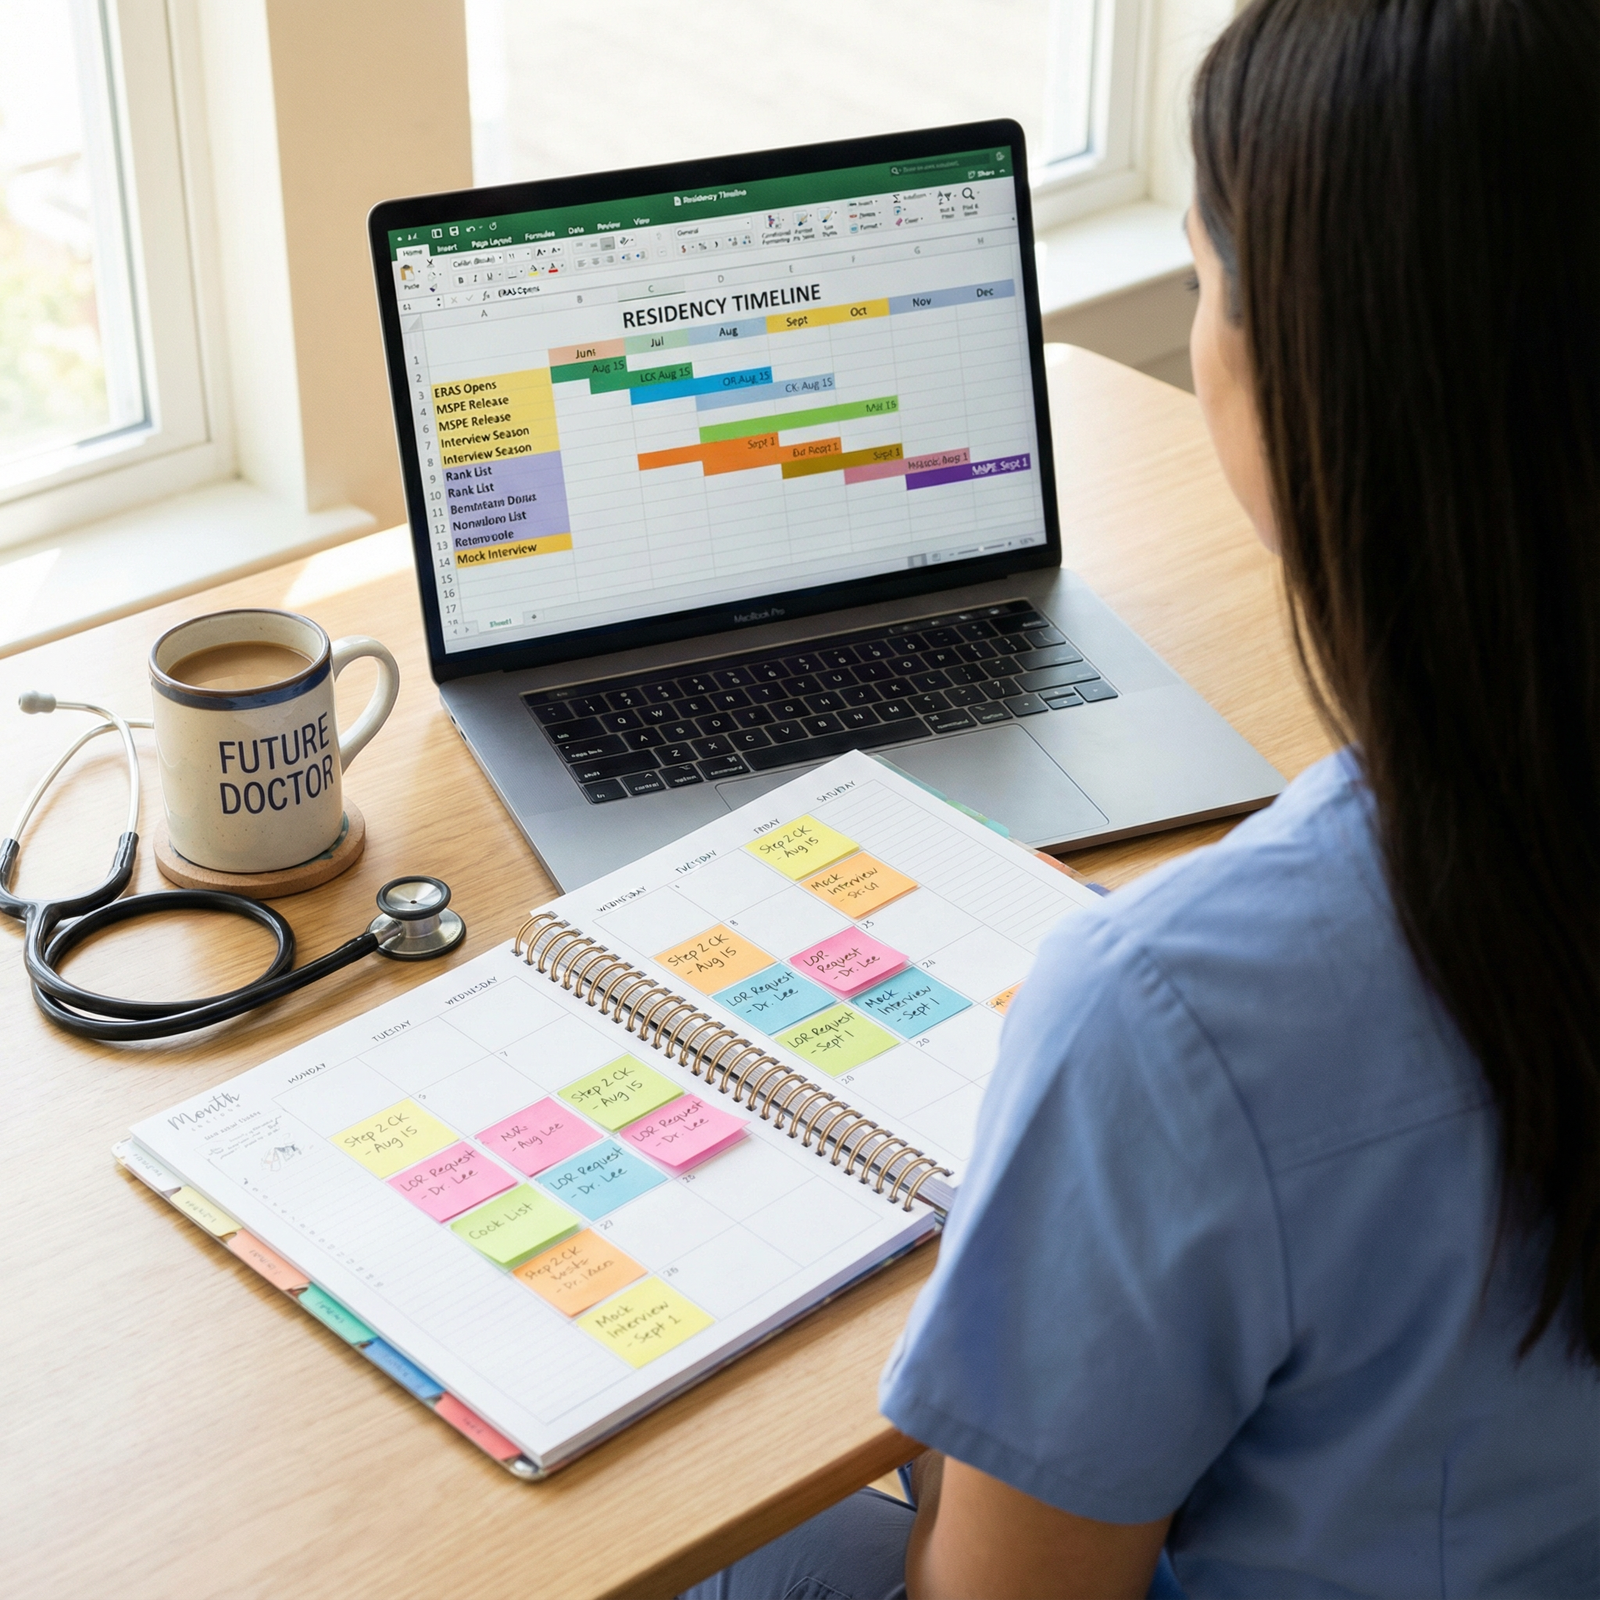
- Present the delay in timeline form
- Offer two remediation options, not just a complaint
Applicant/liaison
- Send a concise escalation summary
- Include timestamps, prior confirmations, and unresolved items
- Ask directly: "Is this still recoverable within the current cycle?"
That question matters. It forces honesty.
Week 4: Decide salvage vs pivot
By now, one of two things should be true:
- the mission is back on track, or
- it is consuming time that should be protecting Plan B
If recovered
- lock dates
- archive updated materials
- confirm all stakeholders received the final version
If not recovered
- activate backup site, backup slot, or backup timeline
- document the failure point
- stop pretending the original plan is fine
False hope is not resilience. It's just delay with better branding.
Day-by-Day Triage When the Clock Hits the Red Zone
This is the part people hate because it removes wiggle room. Good. Wiggle room is how deadlines die.
At this point you should panic only after objective thresholds are met:
- a submission window is missed
- verification fails and remains unresolved
- capacity is still unconfirmed after the stated decision date
- nobody with authority responds after documented follow-up intervals
- the next required step cannot happen without a now-missing prerequisite
Day 1: Confirm actual status
- Check portal, email, and shared tracker
- Verify whether the delay is real or just not yet updated
- Ask one direct question: "What exact item is preventing progression today?"
Day 2: Gather proof
- Pull emails
- Save screenshots
- Note timestamps
- Confirm file names and versions
- Record who owns the next action
Day 3: Send a remediation request
Your message should include:
- current stage
- missing item or blocked action
- proof attached
- requested fix
- deadline for response
Short. Sharp. Specific.
Day 4-5: Follow up and force binary answers
At this point you should stop accepting fluffy language like:
- "We're working on it"
- "It's under review"
- "Should be soon"
Ask:
- Is the packet complete, yes or no?
- Is capacity available, yes or no?
- Is submission still possible this cycle, yes or no?
Day 6-7: Escalate to the next owner
If the issue is unresolved:
- copy the supervising coordinator or program lead
- summarize events in a timeline
- request either immediate remediation or release to alternate planning
Day 8-10: Launch backup planning
This is still fix territory for many delays, but your backup should now be active.
- hold alternate dates if possible
- re-check eligibility for a second option
- prepare duplicate packet materials
- notify mentors or team leads of contingency status
Day 11-12: Red-zone review
At this point you should ask a hard question: is this delay administrative noise, or has the mission become structurally nonviable?
If there is:
- no confirmed capacity,
- unresolved verification failure, or
- no path to on-time submission,
you are no longer "waiting." You are losing the cycle.
Day 13+
Panic isn't drama here. It's recognition.
Immediate escalation is appropriate when:
- a hard deadline has passed
- the organization cannot name a recovery path
- key eligibility requirements remain unmet
- backup options are also about to close
Data to Collect (Match-Timeline Evidence That Actually Moves Decisions)
At this point you should build one single source of truth packet. One file, one sheet, one tracker. Not twelve email threads and a prayer.
Here's what belongs in it:
Core evidence
- Last completed milestone
- Date and time of each handoff
- Email subject lines or correspondence IDs
- Portal status screenshots
- Document versions and revision dates
- Eligibility status logs
- Named owner for the current blocked step
Delay quantification checklist
For every delay, record:
- How many days late is it?
- Which step is blocked?
- Who owns the next action?
- What changed from the original timeline?
- What remediation are you requesting?
- What date do you need the fix by?
- What backup activates if the fix fails?
I've seen weak escalation emails ignored for a week. I've seen strong evidence packets get action in an hour. People respond to organized facts. They ignore fog.
Month-by-Month Guidance (Before, During, and After the Mid-Cycle Drift)
At this point you should think beyond the current fire. Good operators prevent the next one.
Month 1: Build the foundation
- confirm requirements early
- audit document expiration dates
- define owners for each step
- create the shared tracker before anything slips
Month 2: Stress-test setup
- verify availability twice
- confirm staffing and site capacity
- review whether instructions are actually understandable
Month 3: Catch drift early
- compare planned vs actual milestones
- flag any item more than 3-5 days off
- force clarification before delays compound
Month 4: Recover aggressively
- isolate the bottleneck
- run the 7-10 day fix window
- activate backup paths before red-zone collapse
Month 5: Protect outcomes
- lock confirmed commitments
- archive final versions
- close loops with every stakeholder
Month 6: Debrief and archive
- document what failed
- keep templates that worked
- record response times, bottlenecks, and best contacts
Most mid-cycle delays are fixable. That's the reminder. But they're only fixable when you stop treating anxiety like analysis. Track the stage. Name the owner. Quantify the delay. Request a specific remedy. Then, if the thresholds are truly red, escalate without apology.
And after the cycle ends, don't just move on. Debrief it. Archive it. Learn from it. The calmest next cycle is usually built from the messiest last one.